LSI Keyword Generator Myth vs. Modern Semantic SEO
A debunk-and-deliver guide to the LSI keyword generator myth: why Google doesn't use Latent Semantic Indexing, how legacy term checklists hurt AI Overview visibility, and how live SERP entity mapping replaces them from research through CMS publishing.
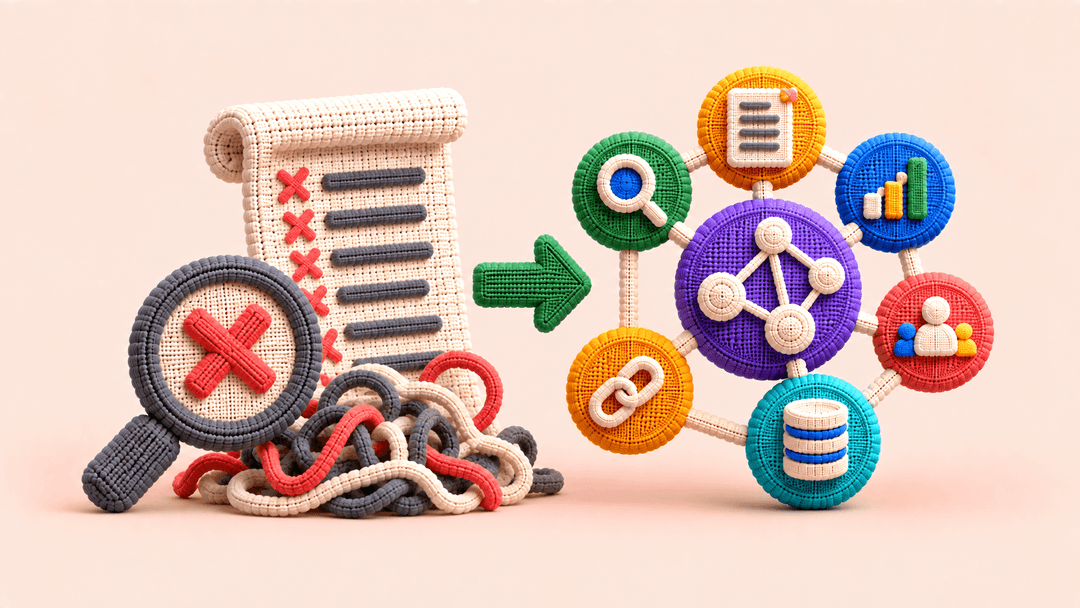
SEO teams keep burning billable hours on an LSI keyword generator, forcing lists of "LSI keywords" into briefs even though Google's own search advocates have said for years that Latent Semantic Indexing plays no role in ranking. Optimizing for a 1980s indexing concept doesn't help your rankings. It just wrecks readability.
Here's the part that should bother you more, because it hits the numbers you report on. Recent search data shows pages built around legacy LSI checklists saw 28% lower visibility in AI Overviews than pages built on entity-based semantic structures. The tool you're using to "add depth" may be quietly suppressing the content it's grading.
This piece debunks the myth first, then covers what modern search actually evaluates and how to automate it, so your writers stop checking boxes and start answering the query.
The Reality of LSI Keywords: What Search Engines Actually Use
Why Google Disavowed Latent Semantic Indexing
Google Search Advocate John Mueller has stated directly that there's no such thing as LSI keywords, and that advice telling you to use them is incorrect. Yet optimization tools keep grading content against arbitrary term-density metrics anyway. That contradiction is the entire reason this topic stays confusing: Google disavows the term while software vendors keep marketing it, and practitioners get caught in the middle.
1980s Database Math vs. Neural Matching
LSI was patented in 1989 for small, static document collections. It has no mathematical architecture for scaling to the dynamic web, which is why modern search runs on systems like BERT, MUM, RankBrain, and neural matching instead. Those systems interpret topics through entities, attributes, and relationships, not co-occurring word lists.
Here's the dirty secret about most "LSI generators": they don't run latent semantic indexing at all. They scrape Google Autocomplete suggestions, People Also Ask boxes, or basic co-occurrence data, then repackage it as advanced SEO software. You're paying for a term list wrapped in an outdated buzzword.
The pages ranking for this query tell on themselves. Some promote LSI as an essential ranking factor and sell paid term-generation tools while ignoring the official disavowals. Others frame LSI as free supplemental discovery for manual briefs and treat it as plain synonyms.
A third group bolts a basic free generator onto a promise of Knowledge Graph signals. None offers publishing or internal link automation, and none connects to rank tracking, performance data, or AI Overviews. None of them explains why the underlying idea stopped working.
The Risks of Relying on an LSI Keyword Generator
How Forced Keyword Insertion Degrades AI Search Visibility
Legacy tools push writers to insert co-occurring words until a density threshold turns green. In vector search architectures, that forced insertion generates semantic noise instead of signal. That's the mechanism behind the 28% AI Overview visibility drop for LSI-checklist pages.
The operational damage shows up fast. Writers waste hours checking off phrases from a spreadsheet, producing copy that reads like an instruction manual. Worse, an old brief template that forces redundant phrase variations into every subtopic can get landing pages demoted after a Google update.
Picture a marketing director reviewing a freshly published post and spotting unnatural, repetitive phrases dropped in to satisfy an optimization score. The content lead explains the software flagged those exact phrases as mandatory LSI keywords. That standoff between editorial quality and outdated scoring software is completely unnecessary once entity mapping replaces term counting.
Generic AI writers make this worse. Prompt one to "include these LSI keywords" and it manufactures artificial subheadings just to fit an awkward key phrase, damaging brand authority in technical B2B content.
The Shift from Word Counting to Knowledge Graph Entity Mapping
Search engines interpret a topic by identifying its core entities, attributes, and semantic relationships across top-performing pages. Content that covers those entities thoroughly picks up natural vocabulary on its own. There's nothing left for a term tracker to count.
Take a team building a competitor page targeting "best enterprise CRM software." A legacy LSI tool hands them terms like "cheap crm," "crm software application," and "database system," and writers force those exact phrases into subheadings. The result is repetitive, low-authority content. An entity-first approach maps the real sub-entities instead: pipeline analytics, SOC-2 compliance, role-based access control, and third-party API integrations. That page satisfies enterprise buyers and captures topical relevance without forcing a single awkward phrase.
Modern Semantic SEO: What to Do Instead of Chasing LSI Lists
How to Conduct Live SERP Entity and Intent Research
Skip the exported spreadsheet. Analyze what's ranking right now: Google Autocomplete, People Also Ask questions, SERP snippet bolding, and the heading structures of top-ranking competitors. Together those reveal the conceptual entities a page must cover to satisfy intent.
Look for conceptual gaps across competitors, not isolated missing words. If every top result covers a subtopic that your draft skips, that's a real gap. If a random synonym is absent, that's noise.
Most guides tell you to chase every related term a tool surfaces. That's wrong because search engines reward clear entity relationships and complete intent satisfaction, not a higher count of phrases.
Doing this manually for every brief is the bottleneck. SEOSorted's keyword research replaces the standalone generator by analyzing live search results in real time and feeding the primary entities, missing subtopics, and intent structures straight into the content pipeline.
In practice, this is a pre-production job. Automated systems read the top-ranking SERP vectors and extract core entities, subtopic hierarchies, and user intent patterns, so writers start from a map of what the query demands instead of a spreadsheet of stray phrases.
Structuring Content for Comprehensive Topical Authority
Once you've mapped entities, structure the page around intent satisfaction. When a subtopic is thoroughly addressed, the necessary domain terminology and natural synonyms appear organically. You never need to track them.
Writers who stall while manually inserting exact-match secondary keywords end up with awkward sentences and a degraded editorial tone, and the fix isn't a better keyword list. It's dropping the list.
Compare your draft against what competitors cover and note which subtopics it misses. Fixing a missing subtopic moves rankings. Adding one more synonym doesn't.
Stop handing writers a checklist of phrases. Try SEOSorted to draft from live SERP entity maps, so the right terminology shows up without anyone counting it.
Streamlining Semantic Content Production from Research to CMS
Automated Entity Extraction and Brief Generation
In a legacy workflow, someone enters a seed term into a generator, exports co-occurring terms, and tells writers to check off every phrase. That produces mechanical content that ignores intent. In a modern workflow, automated systems analyze top-ranking SERP vectors to pull out core entities, subtopic hierarchies, and intent patterns, and practitioners look for conceptual gaps across competitors rather than isolated word omissions.
Drafting changes too. Instead of stalling while writers wedge exact-match phrases into body paragraphs, the generation system works from live SERP entity maps and writes comprehensive explanations. Necessary terminology, domain vocabulary, and natural synonyms land in the prose because the subtopic demands them, not because a checkbox did.
The time savings are concrete. Take an agency producing forty technical articles a month. Writers there can spend 30% of their billable hours checking term boxes to hit green optimization scores. Automated SERP entity mapping drops brief creation time to zero and lets the drafting engine fold required entities in naturally, speeding up delivery.
Direct CMS Publishing and Contextual Internal Linking
Post-production is where the manual work piles up again: copy-pasting into the CMS, setting up metadata, and searching old posts for internal link spots. That's how teams end up with broken link structures and uneven authority distribution across their pages. Scaling is impossible when every draft needs manual semantic research and manual internal link insertion.
Automated internal linking scans your existing domain and injects contextually relevant links with entity-rich anchor text, and direct CMS publishing pushes finished assets to WordPress or Webflow without the copy-paste step. Once that's running, track entity group visibility rather than individual keyword rankings.
Stop treating semantic research, drafting, and publishing as three separate jobs. Try SEOSorted and run all three in one workflow.
Common questions
No. LSI keywords don't exist as a ranking factor in modern search algorithms. Google uses natural language systems like BERT and MUM rather than 1980s Latent Semantic Indexing. Search engines evaluate entity relationships, topical depth, and search intent satisfaction instead of co-occurring keyword lists.
An LSI keyword generator is software that claims to find words contextually related to a primary query. In reality, these tools rarely run true latent semantic indexing. Most simply scrape Google Autocomplete, People Also Ask boxes, or co-occurring terms from top-ranking search results.
Google Search Advocates have confirmed that search algorithms don't use LSI technology. Latent Semantic Indexing was patented in 1989 for small, static document collections. It cannot scale to billions of dynamic web pages, which makes it obsolete for modern web search indexing.
Analyze live search results pages. Google Autocomplete, People Also Ask questions, SERP snippet bolding, and top-ranking competitors' heading structures reveal the entities needed to satisfy intent. Automated platforms speed this up by running real-time SERP analysis instead of exporting static term lists.
Using one isn't harmful on its own, but treating its output as a ranking checklist is. Most free generators repackage Autocomplete and co-occurring data, so the terms are basic suggestions, not algorithmic signals. Forcing them into copy adds semantic noise instead of topical depth.
Related Reading
6 Best Jasper AI Alternatives for SEO Content
A bottom-funnel comparison of six Jasper AI alternatives for SEO-first content teams evaluated on post-draft execution (live SERP grounding, GEO formatting, automated internal linking, direct CMS publishing) rather than drafting speed alone.
How to Rank in ChatGPT Search: 7 Levers That Drive AI Citations
A technical-depth breakdown of how to rank in ChatGPT Search across seven levers, robots.txt crawler controls, Bing indexation, answer-first content architecture, off-site entity consensus, structured schema, proprietary data, and AI visibility measurement for teams who already know traditional SEO and need the generative-search layer.
What Is AI SEO? The Operational Blueprint for Growth Teams
A senior-level breakdown of what AI SEO actually is beyond prompt engineering: the four-phase execution architecture (keyword clustering, live SERP grounding, schema structuring, automated internal linking) that replaces fragmented tool stacks for SaaS founders, marketers, and agencies.